Repository navigation
i have two gaussian_conditional ,when update model, why one update,another one dont update #217
Description
firstly,thank you for your work!
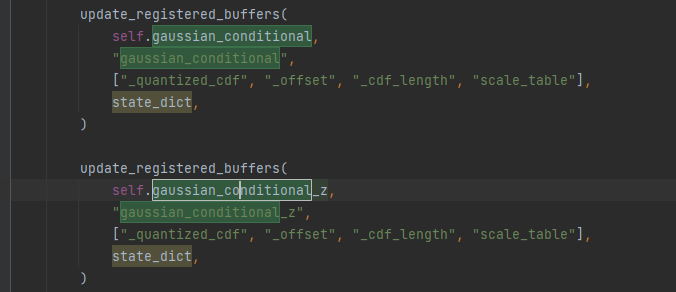
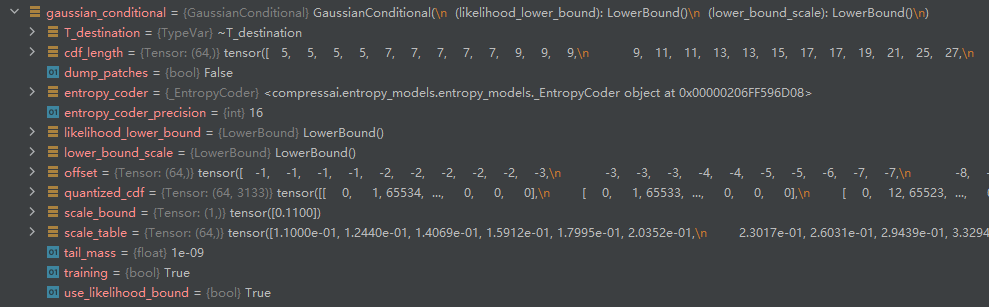
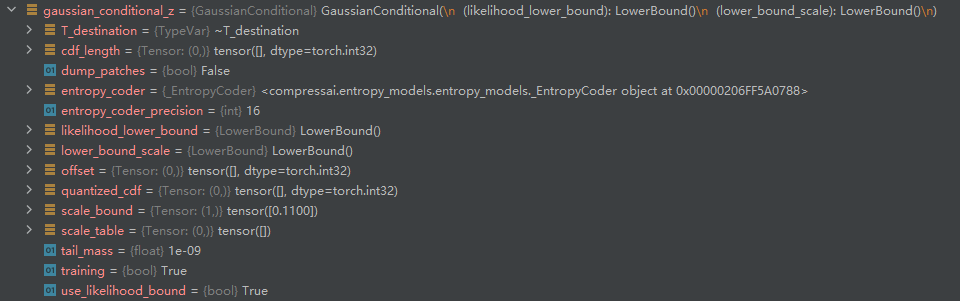
i have two gaussian_conditional ,when update model, why one update,another one dont update
self.gaussian_conditional = GaussianConditional(None)
self.gaussian_conditional_z = GaussianConditional(None)
Activity
YodaEmbedding commentedon Mar 13, 2023
Which version/commit of CompressAI is this? The latest version should handle all these things automatically.
CompressAI/compressai/models/base.py
Lines 62 to 113 in ee91d53
But if you want to figure out what's going on without
git pulling the latest changes:print("This function runs.")statement when the function containing theupdate_registered_buffersis called.load_state_dictis called.super()sometimes may not refer to what you are expecting.battlepeace commentedon Mar 13, 2023
my compressai version is 1.2.0,you say the new version can handle all these things automatically,I want to know if there are any other function updates in the new version?
YodaEmbedding commentedon Mar 13, 2023
Automatic definition of
load_state_dictandupdateNo other significant breaking changes from 1.2.0 to 1.2.4, so upgrading should be easy.
Most users can stop reading here. The section below is for more "advanced usage".
Different scale tables
A single instance of GaussianConditional does effectively the same thing as multiple GaussianConditionals if they all use the same scale table. If you intend on initializing them with different scale tables, then
update()does need to be overridden:For
load_state_dict, we can just inherit the default implementation inCompressionModel.load_state_dict.battlepeace commentedon Mar 18, 2023
I'm sorry I don't quite understand GaussianCondition .you means scale_table Is it a default table that won't change as the input image changes?
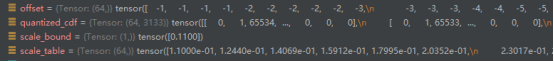
I mean, my two different Gaussian Conditions, one for modeling z and one for modeling y, have the same parameters for Gaussian Conditions. Is this normal?Their parameters both are shown below.
YodaEmbedding commentedon Mar 18, 2023
Yes, their non-trainable parameters should all have the same default initialized values. This is fine.
The section I wrote about "Different scale tables" was just in case you wanted to customize it further.
battlepeace commentedon Mar 18, 2023
Thank you very much for your answer. I have another question. There is a parameter in the code that is quality.For example, in the following model.
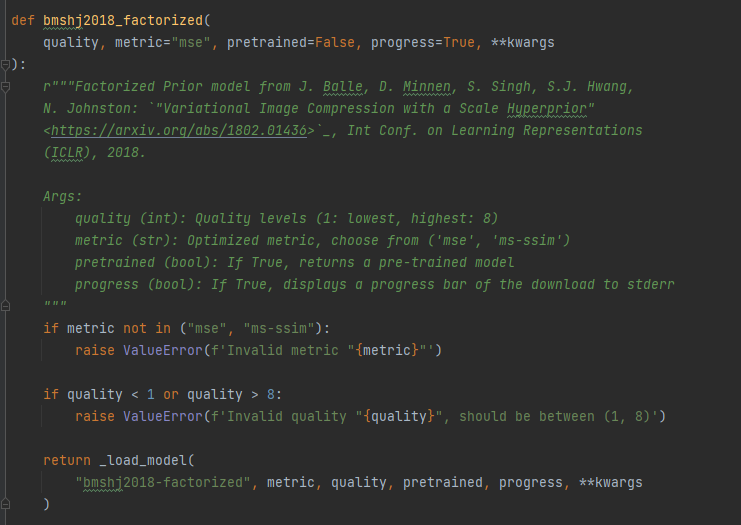
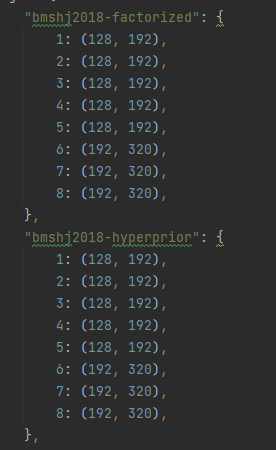
His quality parameters are as follows:
I want to know what this parameter means. Is it N and M in the network model? Do you write this to facilitate selecting different N and M for experiments?
YodaEmbedding commentedon Mar 18, 2023
Yes, these are
N, M, and are used when calling the model's__init__:CompressAI/compressai/models/google.py
Line 242 in ee91d53
The quality parameter refers to different image quality targets that each separate model was trained on. This is done by changing the$\lambda$ tradeoff hyperparameter in the loss function, $L = R + \lambda D$ . The lambdas used for each quality are listed here: https://interdigitalinc.github.io/CompressAI/zoo.html#training
battlepeace commentedon Mar 18, 2023
I don't quite understand what you mean. What you mean is that the qualities of 1-8 are λ Are there different values for?
YodaEmbedding commentedon Mar 18, 2023
The qualities are just a convenient way to number the different trained models which produce small files (quality=1) or large files (quality=8).
The lambdas shown were used to train these models. But you can train with any lambda you want.
battlepeace commentedon Mar 18, 2023
oh,you mean that the specific training lambda is determined when I input training instructions, and the quality I choose will not affect the specific training process. For example, if I specify lambda=0.02, even if I choose quality=1, the lambda during training is still 0.02?
YodaEmbedding commentedon Mar 18, 2023
Yes, that is correct.
battlepeace commentedon Mar 18, 2023
ok,tooo much thanks to you
battlepeace commentedon Mar 18, 2023
sorry,i have a another question.What exactly does aux_loss represent? When I train 10000 images with a batch size of 16 for 100 epochs, in the training output report, The value of aux_ loss is always high, ranging from around 15000 during initial training to around 5500 after 100 epochs. How can it be minimized?
YodaEmbedding commentedon Mar 18, 2023
aux_loss is described here:
Usually, it goes down to ~30 after the first few epochs. It's unusual that it stays large in your case.
Possible scenarios:
train_one_epochthe same as the original from examples/train.py?EntropyBottleneck.quantilesparameters. Do you have multipleEntropyBottleneckinstances in your model?Also, what is the value of the standard RD loss after 100 epochs? Could you also check to see if the bpp from running
eval_modelmatches the bpp_loss? (Run both on the same test image.)battlepeace commentedon Mar 19, 2023
my train_one_epoch is same as original from examples/train.py.
what is s means?EntropyBottleneck() this function is entropy encoded for data, right? However, for example, the ScaleHyperprior model from the h_a obtained z ,z should be modeled using the Factorized Entropy Model. Has EntropyBottleneck() completed this operation?
i use mse to eval model,RD loss is mse loss?this is my output
output.txt
YodaEmbedding commentedon Mar 19, 2023
The RD loss (0.6) looks good. My guess is that at least one of the entropy bottlenecks
.quantilesare not being optimized. Could you post the code for your model definition?EntropyBottleneck encodes each channel separately using some arbitrary distribution trained for each channel. That is indeed a factorized entropy model. It is used on the z in ScaleHyperprior.
battlepeace commentedon Mar 20, 2023
ok
model.txt
YodaEmbedding commentedon Mar 20, 2023
It might be because of the custom
HighLowEntropyBottleneck.If
HighLowEntropyBottleneckis implemented like this:Then try this:Nevermind, there shouldn't be a functional difference between this and what you posted. (But you can give it a try just in case.)
battlepeace commentedon Mar 20, 2023
yes,it like this
class HighLowEntropyBottleneck(EntropyModel):
YodaEmbedding commentedon Mar 20, 2023
The code you posted seems fine to me after a bit of review. I can't understand why it's not reducing the aux loss. The parameters for the aux optimizer are defined as follows:
...however, since what you showed are the default
EntropyBottleneckmodules, they should have.quantilesparameters. The other modules don't have a.quantilesparameter, so no problems there, either...Perhaps just for confirmation, it might be good to verify that the
aux_optimizercontains all the required parameters. I believe these are stored in the variableaux_optimizer.param_groups(or something like that).battlepeace commentedon Mar 20, 2023
your means is i debug it and watch the parameters of aux_optimizer and aux_optimizer.param_groups?
YodaEmbedding commentedon Mar 20, 2023
Yes.
battlepeace commentedon Mar 20, 2023
there may be some trouble?
YodaEmbedding commentedon Mar 20, 2023
I think that looks fine for the untrained model. For the trained model, check:
The values should all be different from
[-10, 0, 10], and look something similar to:i.e. Most channels have a magnitude <1, but there's a couple that have a magnitude of roughly 20.
battlepeace commentedon Mar 20, 2023
how i get it for the trained model?
YodaEmbedding commentedon Mar 20, 2023
Load the trained model using:
battlepeace commentedon Mar 20, 2023
i use update_model to run the checkpoint_best_loss.pth.tar and in this place i code it with
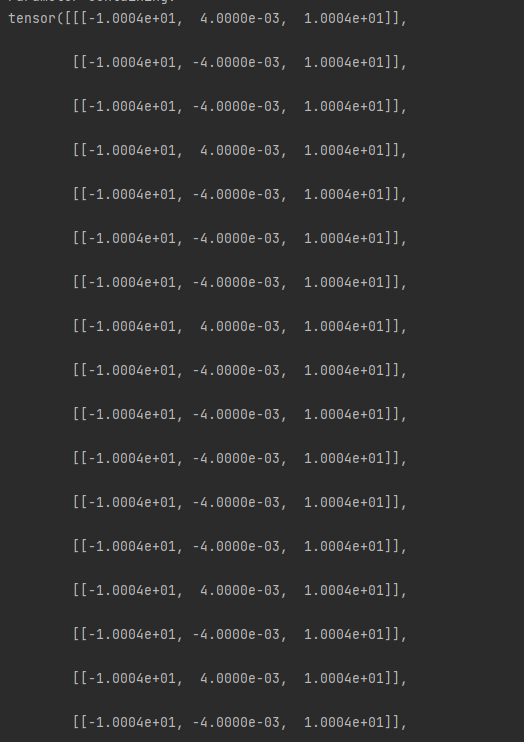
state_dict = load_checkpoint(filepath)
model_cls_or_entrypoint = models[architecture]
if not isinstance(model_cls_or_entrypoint, type):
model_cls = model_cls_or_entrypoint()
else:
model_cls = model_cls_or_entrypoint
net = model_cls.from_state_dict(state_dict)
print(net.entropy_bottleneck.eb_l.quantiles)
print(net.entropy_bottleneck.eb_h.quantiles)
and get these
but this is a test train which just has 2 photos and 2 epoch,if you need a entire training,i will train it ,and send you later.
battlepeace commentedon Mar 20, 2023
another question is i dont know why when i train it more than 100 epochs,the value of test MSE loss will be very unstable and large.you can comprare these two output.
100 epoch output.txt
150epoch output.txt
first one is 100epoch training,test MSE loss will steadily decline
but second one is 150epoch training,test MSE loss acting very strange
Whether this is related to the fact that my test dataset has only 24 images, but I don't think it's the reason. It may be related to learning rate.